API & MCP
MCP server
Connect Honeylog to Claude, ChatGPT, Cursor or any MCP client and let the AI read your traffic data.
The Honeylog MCP server lets an AI assistant read your traffic data directly. Instead of exporting a report and pasting it into a chat, you connect Honeylog once and then ask questions like "which AI agents crawled my pricing page last month" or "which pages got the most bot traffic yesterday".
It uses the Model Context Protocol, so it works with any client that supports it, including Claude, ChatGPT, Cursor and VS Code. Everything it exposes is read-only. No tool can change a setting, delete data or spend money.
#Endpoint
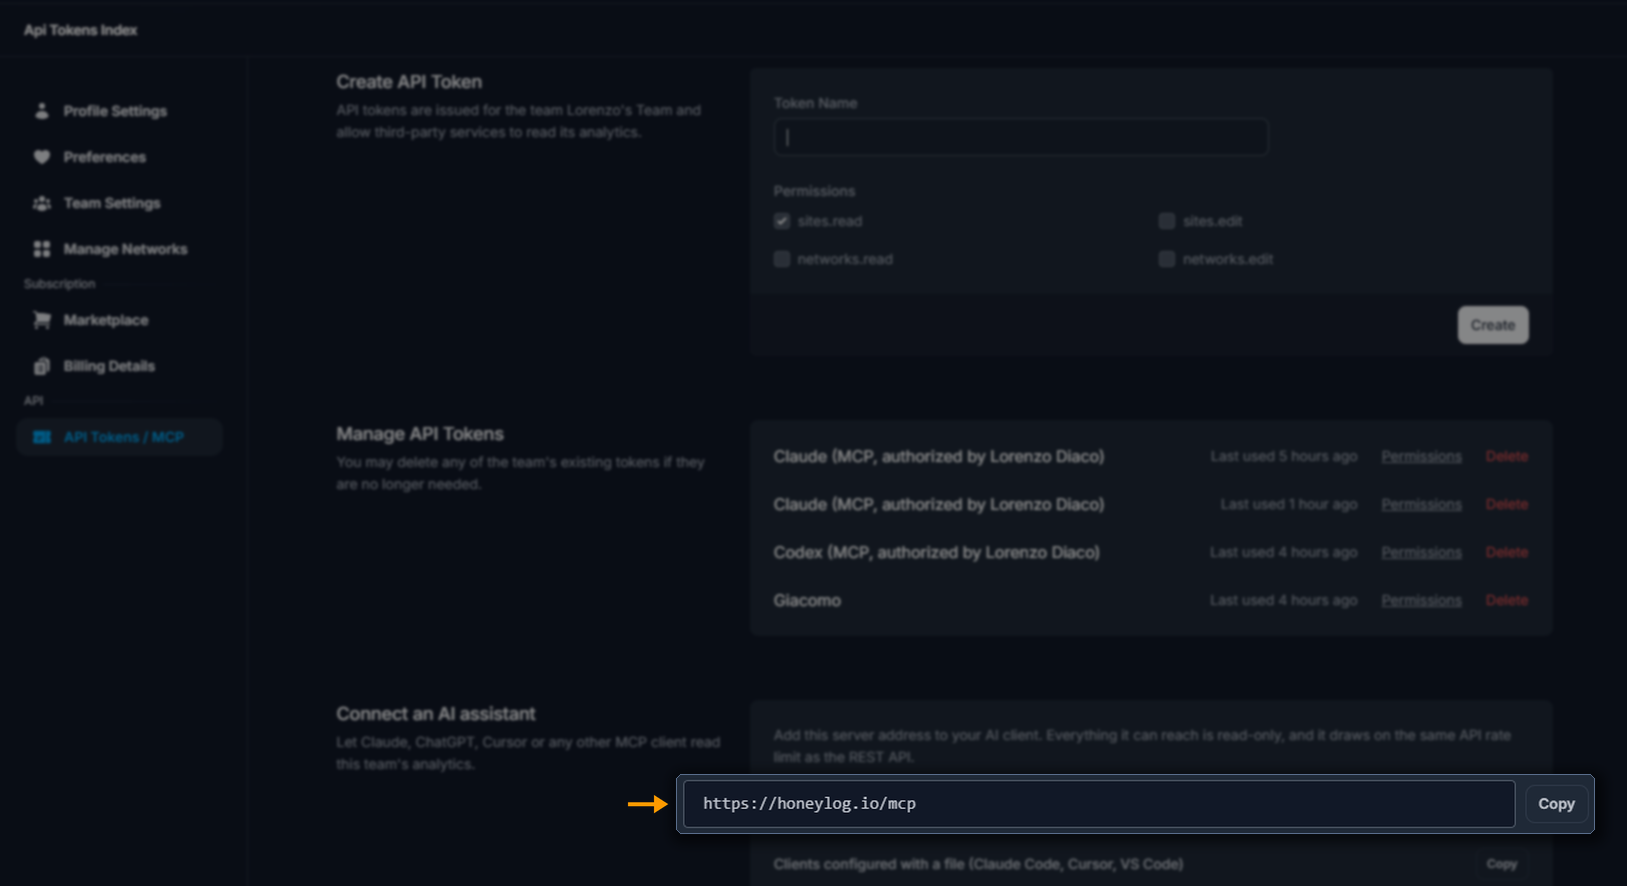
https://honeylog.io/mcp
One address covers every site, custom view and network your token can reach. There is nothing to install.
#Two ways to connect
| Sign in (OAuth) | Paste a token | |
|---|---|---|
| For | claude.ai, Claude Desktop, ChatGPT | Claude Code, Cursor, VS Code |
| You copy | the server address | the server address and a token |
| The token is | created for you when you approve | created by you beforehand |
Either way you end up with a team API token listed under Settings → API tokens, with read access to the team's sites, custom views and networks. Delete it there to disconnect the assistant.
Only team owners and managers can connect a client. The token belongs to the team, not to the person who created or approved it, so it keeps working when someone switches their current team, and it reaches every site in that team.
#Connecting claude.ai, Claude Desktop or ChatGPT
You copy one address and sign in. The screenshots are from claude.ai, but ChatGPT and Claude Desktop work the same way with slightly different wording.
#1. Open the API tokens page
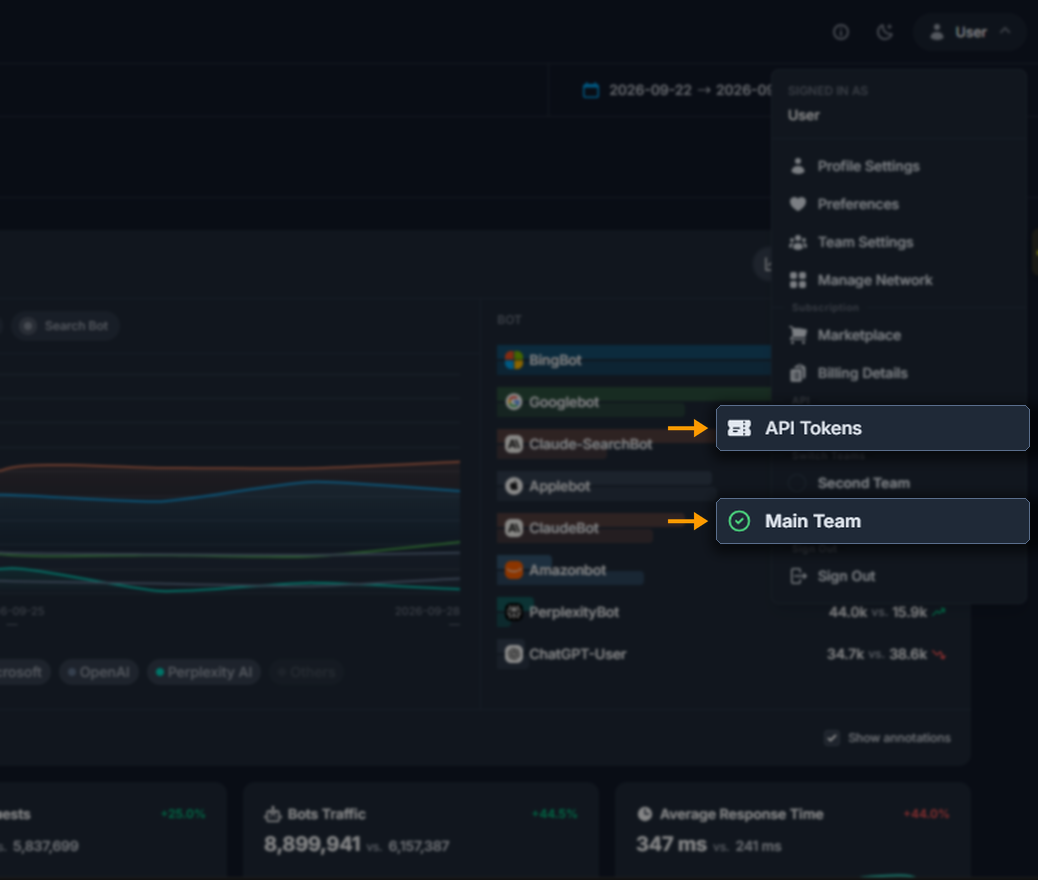
In Honeylog, open the user menu at the top right. Make sure the team you want the assistant to read is the one selected, since the connection will belong to that team, then click API Tokens.
#2. Copy the server address
Scroll to Connect an AI assistant at the bottom of the page and copy the address. You don't need to create a token here, because signing in creates one for you.
#3. Open your client's settings
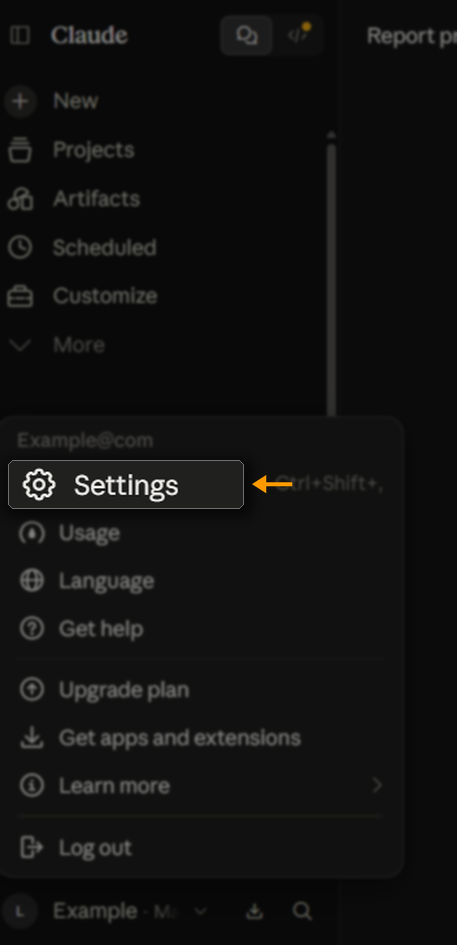
In claude.ai, click your name at the bottom of the sidebar and choose Settings.
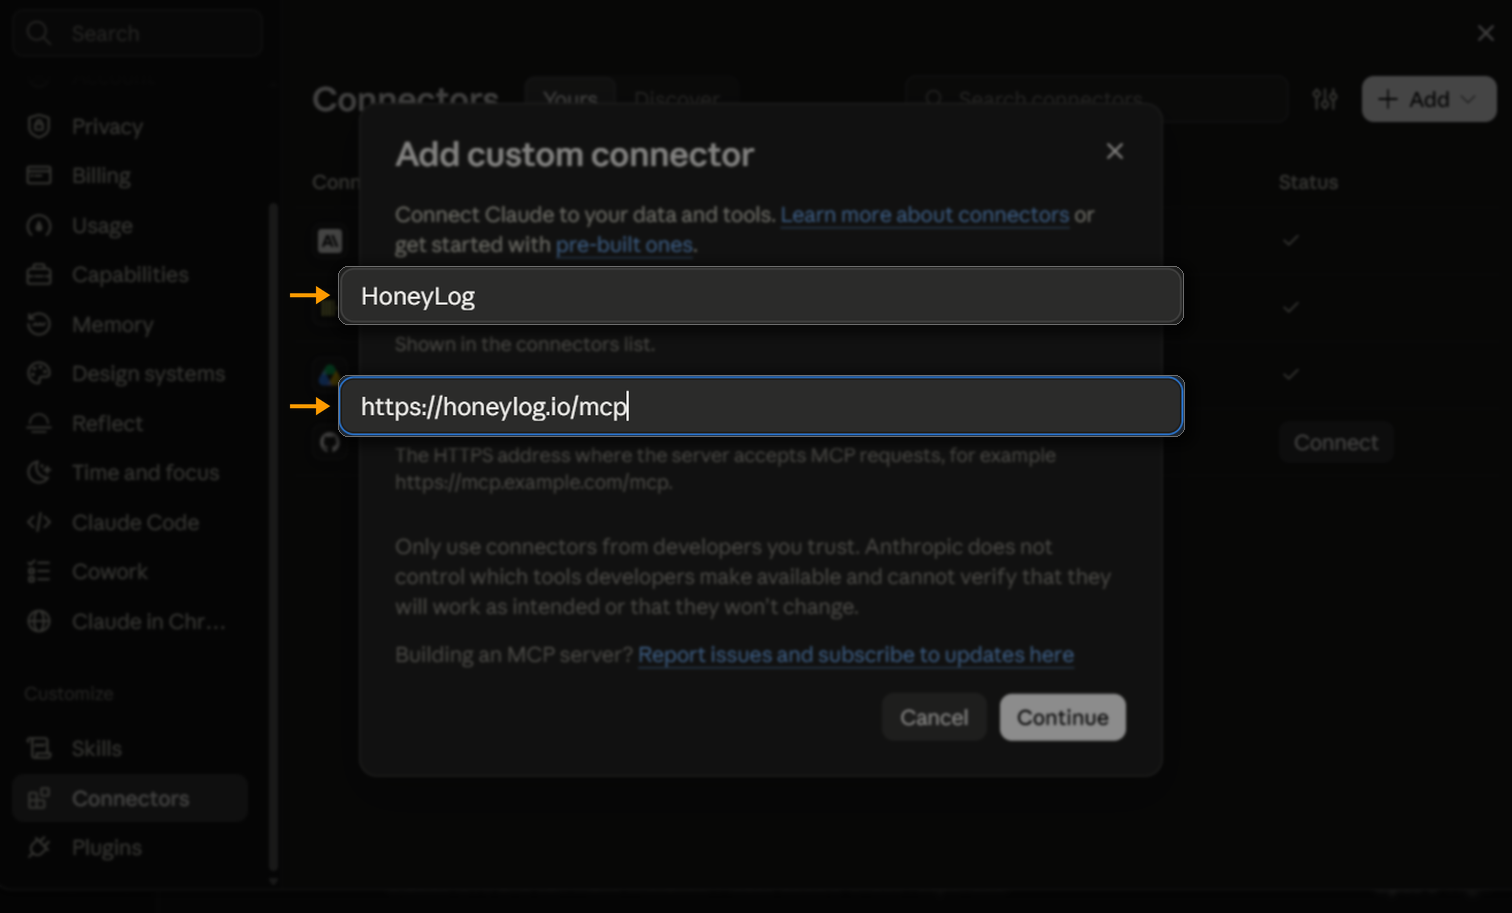
#4. Add Honeylog as a custom connector
Go to Connectors → Add → Add custom connector. Give it a name, paste https://honeylog.io/mcp as the server URL, and click Continue.
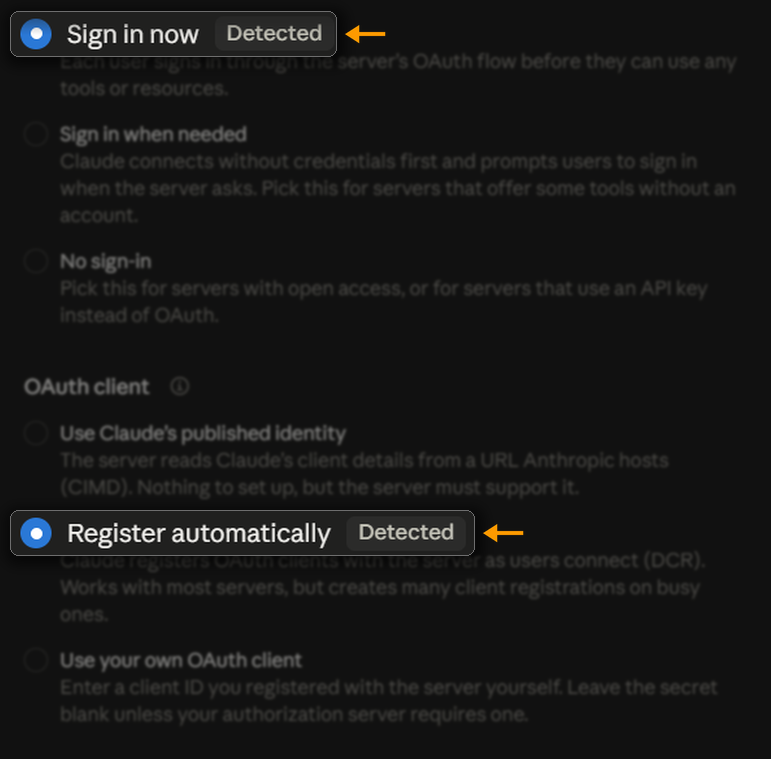
#5. Leave the sign-in settings as detected (Suggested)
Claude reads the server configuration and fills this step in by itself, selecting Sign in now and Register automatically, both marked Detected. Leave them as they are. There is no client ID or client secret to enter, because the client registers itself with Honeylog.
#5b. Or skip the sign-in and paste a token (Alternative)
If you would rather give the client a token yourself, pick No sign-in in the step above, then create the token in Honeylog and pass it as a request header.
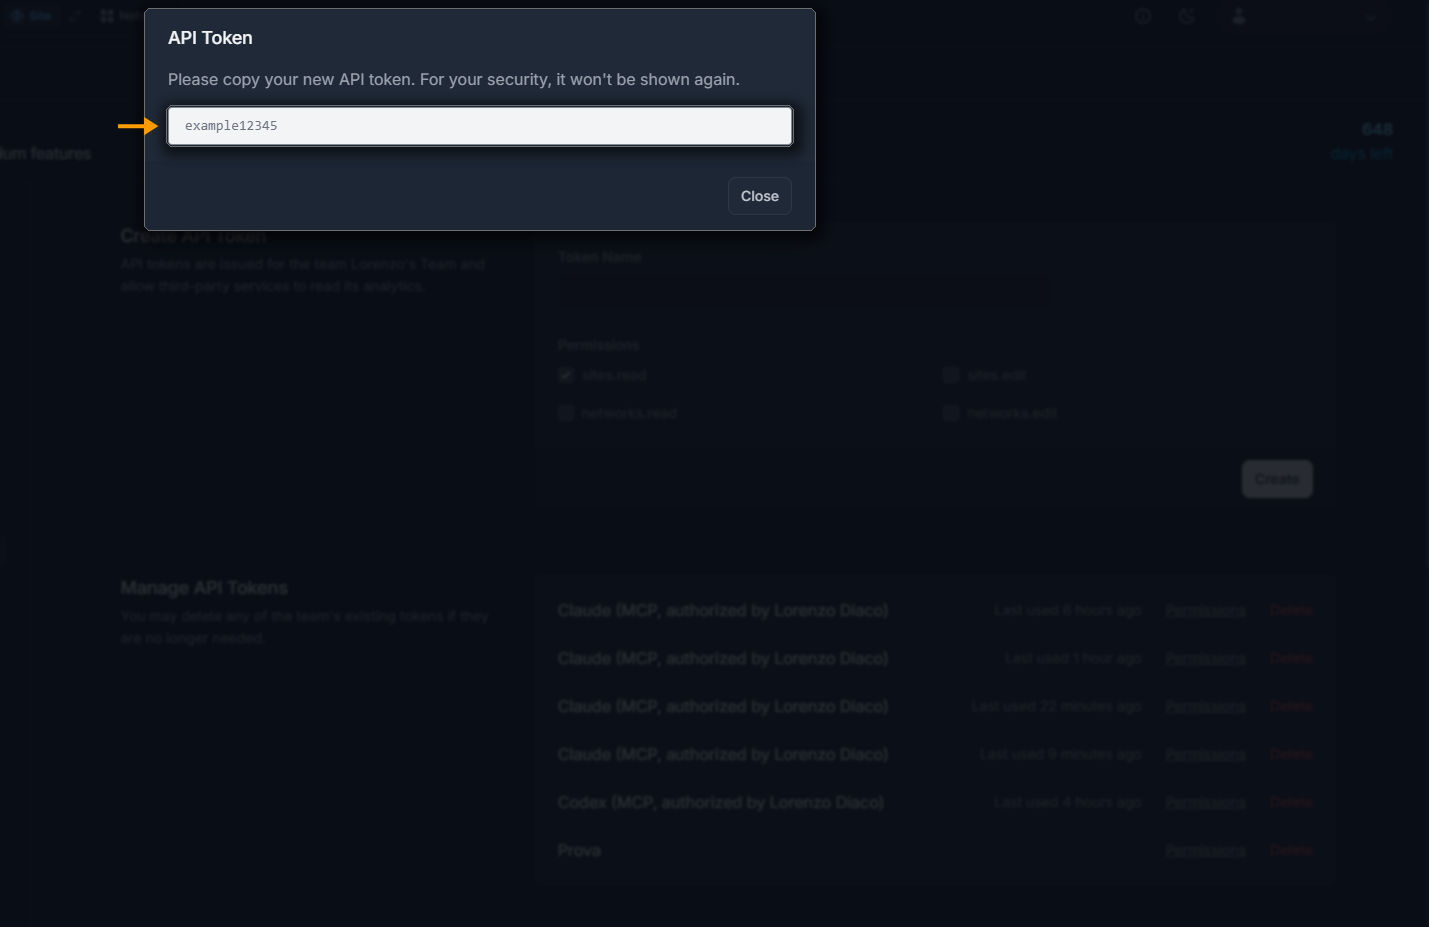
Back on the API tokens page, type a token name, tick sites.read, or networks.read if the assistant should reach networks too, and click Create. Copy the token from the dialog. It is shown once and never again.
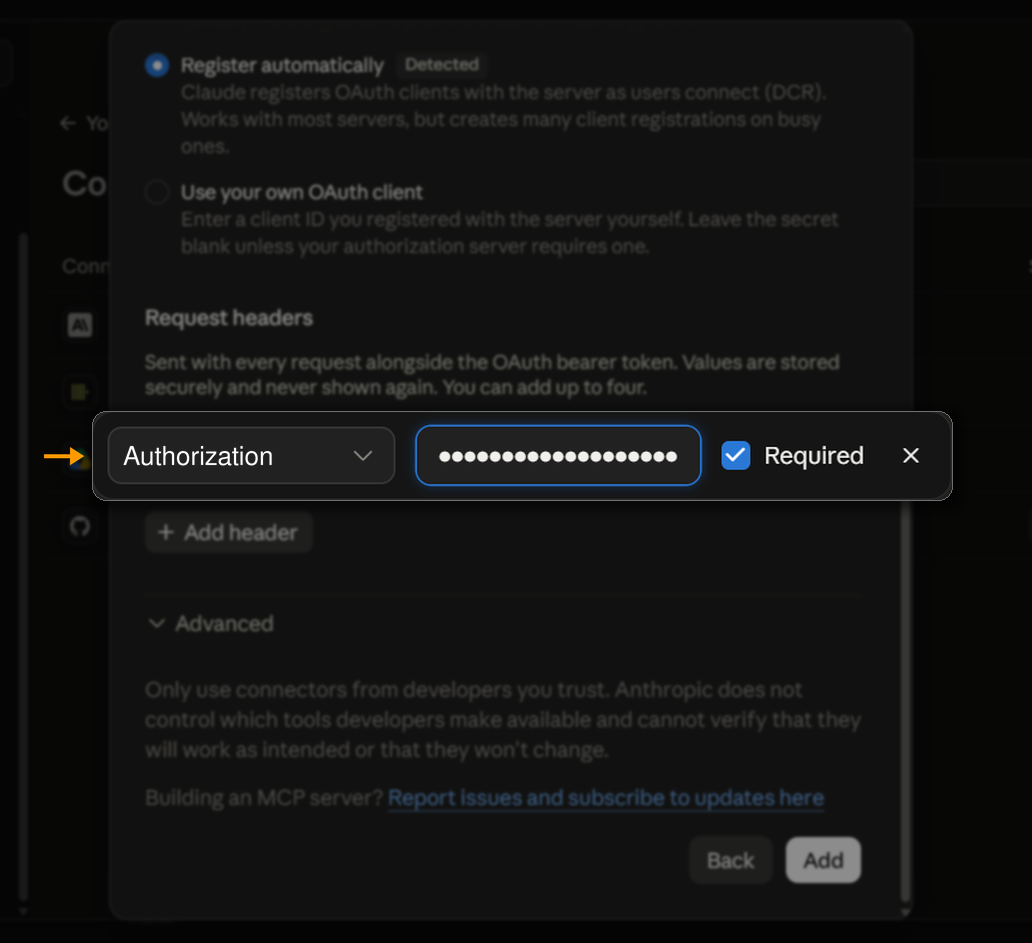
Then, under Request headers in the connector dialog, add a header named Authorization with the value Bearer YOUR_TOKEN. Claude stores the header securely and never shows it again, so keep the token somewhere safe if you want to reuse it.
#6. Approve the connection
Click Add. A Honeylog window opens and asks whether the assistant may read your analytics. Sign in if you are asked to, choose the team it should read, and click Allow access.
The page lists what you are granting: read access to that team's sites, custom views and networks, no ability to change anything, calls counted against the team's normal API rate limit, and a token you can revoke whenever you want.
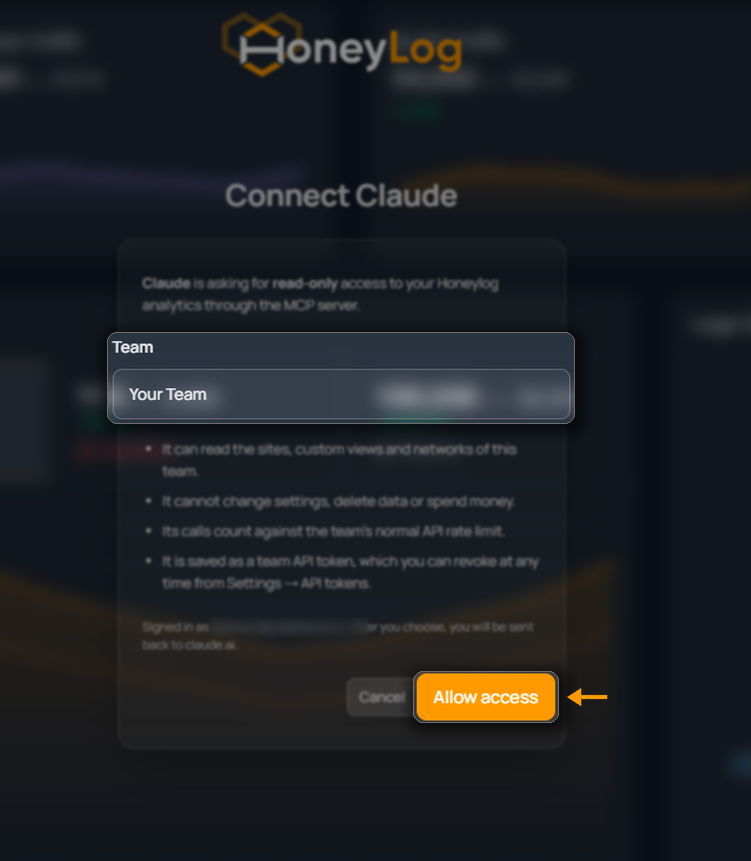
#7. You're connected
Honeylog sends you back to the client, which confirms the connection. You can start asking questions right away.
The connection now appears under Settings → API tokens as Claude (MCP, authorized by <your name>), along with the last time it was used. Delete that entry to disconnect the assistant.
#Configuring a client with a file
Claude Code, Cursor and VS Code are configured with a file rather than a dialog, so they take a token you create yourself.
- Open Settings → API tokens and create a token with
sites.read, ornetworks.readif you want the assistant to reach networks too. - Copy it from the dialog while it is on screen.
- Give it to your MCP client as a bearer token:
{
  "mcpServers": {
    "honeylog": {
      "type": "http",
      "url": "https://honeylog.io/mcp",
      "headers": {
        "Authorization": "Bearer YOUR_TOKEN"
      }
    }
  }
}
The Connect an AI assistant section on the API tokens page has both the address and this snippet ready to copy.
#What the assistant can do
There are six tools. The first two let the assistant find out what to ask for, and the other four answer the questions.
| Tool | What it does | REST endpoint it calls |
|---|---|---|
honeylog_list_sites |
Lists the sites, custom views and networks the token can read, with the identifier the other tools need | GET /api/v1/sites |
honeylog_describe_fields |
Lists the metrics and dimensions one site accepts, with their meaning and allowed values, or the raw-log columns | GET /api/v1/{wireable}/fields |
honeylog_traffic_timeseries |
How traffic moves over time, for one or more metrics, with an optional comparison period | GET /api/v1/{wireable}/stats/views |
honeylog_traffic_breakdown |
Which pages, bots, countries, browsers or referrers account for the traffic | GET /api/v1/{wireable}/stats/pages |
honeylog_raw_logs |
The individual requests behind the reports, such as the exact URLs a crawler fetched, over short windows | GET /api/v1/{wireable}/raw-logs |
honeylog_raw_logs_timeseries |
How many requests arrived per minute, hour or day, counted on the same raw requests, over short windows | GET /api/v1/{wireable}/raw-logs/timeseries |
Most assistants call the first two on their own before answering, so you rarely need to mention them. Just ask your question.
Each tool is a wrapper over the REST endpoint in the last column. It forwards the call and hands back that endpoint's answer unchanged, inside the usual data and meta object. There is no separate path to your data, so whatever the API refuses, the assistant is refused too.
Some things you can ask:
- Which AI crawlers visited the site last week, and which pages they went to.
- Whether bot traffic went up compared with the previous month.
- Which pages return the most 404s to crawlers.
- Which countries the suspicious traffic comes from.
- Which exact URLs GPTBot requested in the last hour.
- At what time this morning a crawler burst started, minute by minute.
#Rate limits
MCP calls and REST calls share one budget. Every tool call spends one call from your plan's normal API allowance, counted against the same limit as if you had called the REST API yourself. That includes the two calls the assistant makes to find your sites and fields, since those go through the API as well. In practice a question costs the one call that answers it, plus, at most once per conversation, the two that tell the assistant what to ask for.
There is no separate MCP quota and no separate plan gate. If your plan includes API access, it includes the MCP server. A plan without API access returns an error explaining that, and hitting the per-minute limit returns an error saying when to retry.
#Good to know
- Dates are interpreted in the site's own timezone, which every answer repeats, so results match what you see in the dashboard.
- Default window is the last 7 days when the assistant does not ask for a specific range. For the usual periods, such as yesterday, the last 30 days or last month compared with the month before, the assistant names the period and Honeylog works out the dates in your site's timezone, the same way as the dashboard date picker.
- Raw logs come back 10 rows at a time unless the assistant asks for more, at most 100 per call, over the last 24 hours unless it asks for another window of at most 8 days. For counts and trends the other tools are cheaper, and the assistant is told so.
- Read-only is enforced on the server. Connecting an assistant cannot change your configuration or your billing.
- Connecting twice creates a second token rather than replacing the first, so if you reconnect a client, delete the old entry to keep the list readable.
- If an assistant reports that it cannot find your site, check that the token has the right permission for the resource:
networks.readis needed for networks,sites.readfor sites and custom views.